Table of Contents
Introduction: Context Engineering Starts with Content Readiness
Context engineering can assemble the right information, but it cannot make bad source content trustworthy.
Consider an enterprise compliance assistant that retrieves five versions of the same policy. One version remains current. Another contains outdated requirements. A third remains in draft status. Two others lack clear ownership.
The AI can retrieve every document successfully. Retrieval alone cannot establish which source it should trust. The system needs signals for authority, version, approval status, applicability, ownership, and access.
This creates a fundamental distinction for enterprise learning leaders. Machine accessibility alone is not enough. Content also needs sufficient context to support appropriate AI use.
Gartner’s 2025 research found that 63% of organizations either lacked suitable AI data practices or remained unsure if they had them. Gartner also predicted that organizations would abandon 60% of AI projects unsupported by AI-ready data through 2026.
While Gartner’s research addresses enterprise AI data readiness broadly, the same principle applies to learning content: AI cannot reliably use information that remains poorly governed, outdated, or ambiguous.
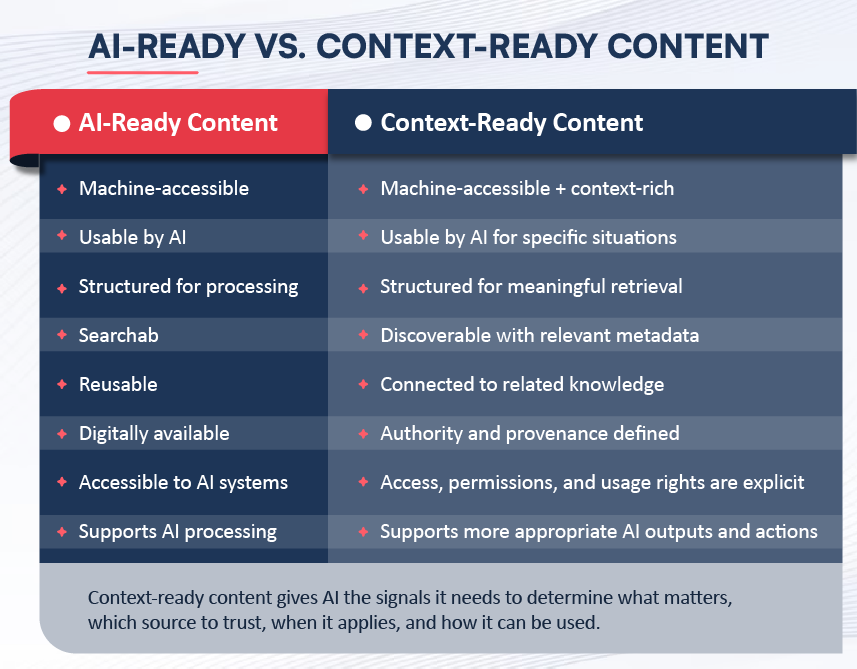
AI-ready content is machine-accessible and usable by AI. Context-ready content goes further. It combines machine accessibility with metadata, authority, relationships, applicability, and permissions. These signals help AI determine what information matters, which source to trust, and how that information applies.
The strategic question is therefore not only whether content is AI-ready. It is whether the content can provide reliable context for specific AI use cases.
Why Context Engineering Cannot Fix Weak Content Infrastructure
Context engineering works with the information available. Weak information therefore creates weak context.
Retrieval alone does not establish authority. Reliable use also depends on source priority, version history, approval status, applicability, ownership, and access signals. Without these controls, the problem starts upstream. The content infrastructure needs attention before AI can deliver reliable results.
Content Debt Can Become AI Debt
Content debt existed long before generative AI. Organizations accumulated fragmented files, duplicate assets, inconsistent metadata, and outdated materials. These issues previously affected search, maintenance, and reuse.
AI now makes these problems more visible. The same debt can produce unreliable answers and poor grounding. It can also create duplicate retrieval and higher review effort. This creates a costly cycle. Weak content requires greater human oversight. Greater oversight can slow AI adoption. Slower adoption can reduce the return on AI investments.
Learning leaders should therefore separate two improvement paths. One improves how AI uses existing information. The other improves the information itself. Context engineering supports the first path. Content modernization, enrichment, governance, and lifecycle management support the second. Enterprises need both capabilities to scale AI effectively.
What Makes Learning Content Context-Ready?
Good learning content does not automatically become context-ready. Instructional quality remains important. AI-enabled learning also requires additional content capabilities. Context-ready content should support human and machine use. It should also help AI understand meaning, authority, applicability, and permitted use.
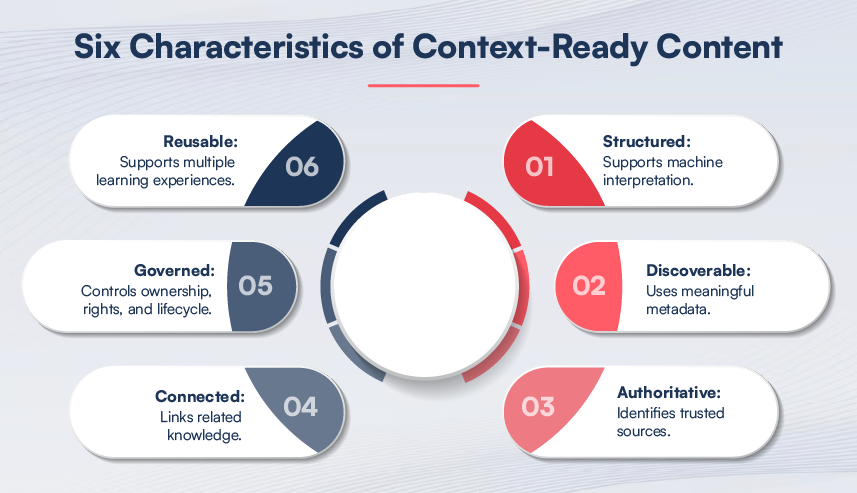
Six characteristics below provide a practical foundation: Structured, Discoverable, Authoritative, Connected, Governed, and Reusable. Rights and Quality Controls cut across these characteristics and help determine whether organizations can use content appropriately.
1. Structured
Meaningful structure helps AI interpret content accurately. Headings, sections, learning objects, and relationships should remain identifiable. Modular structures can support targeted retrieval and reuse. However, teams should not break content into small objects at the expense of instructional meaning. The structure should preserve the narrative, sequence, and context that learners need.
2. Discoverable
AI must locate relevant information efficiently. Metadata provides important discovery signals. Useful metadata can include role, skill, topic, audience, proficiency, language, and learning objective. Provenance and applicability add further context. They help AI determine where information comes from, who it serves, and when it applies. Semantic relationships can also improve discovery.
3. Authoritative
AI should not treat every source equally. Approved content should outrank drafts. Current material should outrank archived versions. Organizations should define source authority and ranking rules. These signals help AI select more trustworthy information.
4. Connected
Learning content rarely exists alone. It connects with skills, roles, products, policies, processes, and workflows. These relationships give AI more context around the content. They help AI move from answering “what is this?” to understanding “who needs this, when, and in what context?” This supports more relevant recommendations, learning pathways, and performance guidance.
5. Governed
Governance keeps content trustworthy over time. Ownership, versioning, approval, and review cycles should remain clear. Governance should also define access, usage rights, and permitted AI use. Structured content may still remain restricted for retrieval, transformation, or redistribution.
6. Reusable
Context-ready content should support multiple experiences. One authoritative source can power a course module, AI answer, practice scenario, personalized recommendation, workflow guidance, or assessment feedback. Reuse reduces repetitive development and helps organizations maintain greater consistency across learning experiences.
Context Readiness Goes Beyond Metadata
Metadata alone cannot make content context-ready. Context readiness also depends on clear signals for provenance, authority, version history, permissions, rights, and applicability.
Rights deserve particular attention. Learning content may contain licensed or customer-owned intellectual property. Some assets may allow retrieval but restrict redistribution. Others may allow internal use but restrict transformation. AI systems need these constraints as part of their context.
Applicability matters too. A policy may apply to one region. A product guide may apply to one version. A certification rule may apply during a specific period. Content should expose these boundaries clearly so AI can use information appropriately.
Rights and quality controls should therefore work as cross-cutting controls across the six characteristics. They help determine whether AI can access, transform, and use content within defined boundaries.
From Content Assets to Context Assets
A course should no longer be viewed only as a finished delivery asset. Its underlying knowledge, examples, assessments, metadata, and practice elements can become reusable context for multiple AI-enabled experiences.
Instead of creating separate content for every experience, organizations can build from authoritative knowledge sources. AI can then retrieve and assemble relevant elements for different learner needs and workflows.
Consider authoritative product knowledge as the source. That knowledge can support a course module, AI-generated answer, practice scenario, personalized recommendation, workflow guidance, or assessment feedback.
One controlled source can therefore support multiple experiences without creating disconnected versions of the same knowledge.
From One Course to Multiple Learning Experiences
| Traditional Content Model | Context-Ready Content Model |
|---|---|
| Course-centric | Knowledge + experience-centric |
| Fixed delivery | Reusable across multiple delivery modes |
| Large content packages | Structured content with meaningful relationships |
| Limited reuse | Multi-experience reuse |
| Descriptive metadata | Rich contextual metadata |
| Manual recommendations | Context-aware recommendations |
| Periodic/manual lifecycle management | Governed, ongoing lifecycle management |
Organizations do not need to rebuild every asset. Leaders can start with high-value content collections. They can prioritize content supporting specific AI use cases.
How Enterprise Learning Leaders Can Assess Content Readiness
Content readiness requires more than a content inventory. Leaders need to understand both capability and constraint. Start with the intended AI use case. Identify the content required for that use case. Then assess the content and supporting infrastructure. Finally, prioritize gaps that could limit business value.
A Diagnostic Content-Readiness Framework
| Diagnostic Area | What to Examine | Leadership Question |
|---|---|---|
| Structure | Format, structure, modularity, semantic relationships | Can AI interpret the content without losing meaning? |
| Discovery | Metadata, taxonomy, searchability, applicability | Can AI find content that fits the situation? |
| Authority | Approval, provenance, source quality, ranking | Can AI identify the source it should trust? |
| Connections | Skills, roles, topics, products, processes, workflows | Can AI understand how the content relates to the use case? |
| Governance | Ownership, lifecycle, versioning, review | Can teams keep the content current and reliable? |
| Reuse & Portability | Modularity, interoperability, portability | Can one source support multiple experiences? |
Rights, permissions, accessibility, quality, and compliance should apply across all six areas. These controls determine whether AI can access and use content within defined boundaries.
Evaluate Source Quality and Authority
Not every internal document deserves equal trust. Organizations should distinguish approved content from drafts, archived material, and user-generated content. They should define source-ranking rules so AI can prioritize appropriate information and escalate uncertainty for human review.
Treat Rights and Permissions as Readiness Factors
Rights can limit AI retrieval, transformation, and redistribution. Leaders should determine what AI can access, what it can transform, and what it can use in generated outputs. These permissions should remain visible wherever possible.
Prioritize High-Value Content
Organizations rarely need enterprise-wide modernization first. Start with content that supports priority AI use cases, such as compliance, onboarding, product training, or performance support. Assess representative content, identify recurring gaps, and prioritize improvements based on business impact and AI requirements.
How Harbinger Helps Build the Foundation for Context Engineering
Enterprise leaders need evidence before scaling AI use cases. They also need a clear path from identified gaps to business outcomes.
Harbinger’s Content Intelligence Infrastructure Assessment provides an entry point for evaluating content readiness. It examines the infrastructure and practices that support content-led AI and identifies constraints across content structure, delivery, stewardship, and quality.
The assessment should lead to a prioritized roadmap tied to specific AI use cases and business priorities, not just a readiness score. Leaders can use the findings to determine which content to modernize, which governance gaps to address, which permissions to clarify, and which high-value use cases to prioritize.
Harbinger’s eLearning content development services can support content transformation and modernization as organizations address these readiness gaps.
This creates a practical path: Assess → Prioritize → Modernize → Govern → Scale
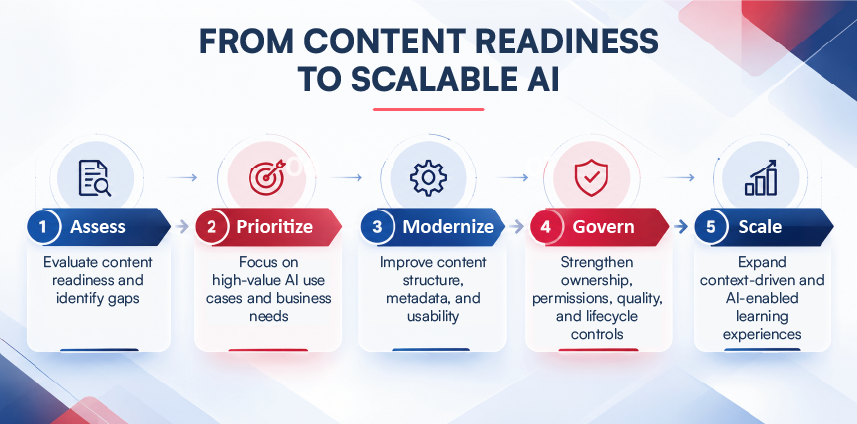
Organizations can strengthen priority content and expand AI-enabled learning experiences as readiness improves through Harbinger’s AI-based learning solutions.
Organizations can evolve their learning ecosystems incrementally. They can retain valuable LMS investments, modernize priority content, and connect learning content with broader enterprise knowledge. This staged approach helps them strengthen the foundation before expanding context-driven learning experiences.
Conclusion
Context Engineering Starts with Content Readiness: Building Reliable AI for Enterprise Learning
Context engineering can improve AI relevance, but it cannot make weak content trustworthy. Without clear authority, applicability, rights, and governance, AI may struggle to use information appropriately. The goal is content that fits its intended AI use. Stronger foundations can improve relevance, reduce review effort, support reuse, and build trust.
So, does your content have the structure and context your AI use cases need?
Pick one priority AI use case and assess whether the content behind it is structured, authoritative, connected, governed, permission-aware, and reusable. The gaps will show what needs to change before you scale context engineering.
Harbinger’s Content Intelligence Infrastructure Assessment can help you identify those gaps and define the next practical steps toward AI-ready, context-ready content.
Ready to assess your content foundation? Book a consultation with us.
Write to contact@harbingergroup.com or visit https://www.harbingergroup.com/contact-us/.