Somewhere in your market today, a customer is asking an AI assistant a question your organization has answered better than anyone for years. The assistant replies in seconds, fluently, often accurately. It may even be drawing on your work to do it. What decides whether your knowledge is used well in that moment is not the model. It is whether the knowledge inside your catalog can actually be reached.
For publishers, the real AI bottleneck is becoming clearer. It is the distance between the finished publication and the underlying knowledge. A publisher may own extraordinarily valuable IP, but if the smallest usable unit is still a PDF, a book, a course, or a SCORM package, an AI application cannot reliably use that knowledge at the granularity it needs. The value is real. The challenge is making that value accessible at the level these tools require.
This does not diminish what publishers have built. Authoritative content matters more in a market flooding with synthetic text, not less. Scale, brand, distribution, and authority still count. What is changing is that AI adds a new layer on top of them: whether that knowledge can be understood, governed, and assembled by machines as reliably as it is by people. The moat is not disappearing. It is expanding to include machine usability, and that is the part most catalogs were never designed for.
Four ideas sit underneath that shift, and they are worth holding onto:
- Catalog scale is not the same as knowledge accessibility.
- Content engineering prepares knowledge; context engineering activates it.
- AI turns rights into a runtime decision.
- Publishers increasingly need to design knowledge for assembly, not just delivery.
Catalog scale is not the same as knowledge accessibility
Publishers have spent decades scaling one thing: the size and reach of the catalog. AI increasingly rewards a different kind of scale, the accessibility of the knowledge inside it. These are two different achievements, and success at the first does not deliver the second.
What we are beginning to see across modernization and migration programs makes this concrete. We have worked with catalogs where the intellectual value of the content is very high, yet extracting a single concept reliably means traversing a finished course package, a presentation layer, and inconsistent metadata. AI does not make that complexity disappear. It exposes it. The same programs surface what is fairly called content debt, the counterpart to technical debt: years of content trapped in inconsistent structures, taxonomies, metadata models, formats, and rights treatments. Inconsistencies that were entirely acceptable when content was read by people now degrade retrieval, grounding, and reuse the moment a machine tries to use them.
AI is making content debt visible in much the same way cloud and API modernization exposed technical debt.
This is often a consequence of reasonable decisions made 10 to 15 years ago. Systems optimized for desktop publishing, course delivery, or document distribution were the right choice at the time. But content embedded in a presentation layer, duplicated across products, or tightly coupled to how it renders is harder for a machine to reach now. That is not a criticism of legacy architecture. It is what happens when a new consumption model arrives.
There is a useful way to name the underlying problem: the publication boundary. Most publishing systems are built to create and deliver a finished object, a book, journal, course, assessment, or video. AI often needs something smaller and more specific: an explanation, a concept, a claim, an example, an assessment item, a piece of evidence, or the relationship between two ideas. AI does not consume publications the way readers do. It consumes knowledge units and the relationships between them. The next publishing architecture will therefore manage both the finished publication and the knowledge objects inside it.
Content engineering prepares knowledge; context engineering activates it
Two disciplines are often confused, and the distinction matters. Content engineering makes knowledge usable: structured, modular, well-described, and machine-usable rather than locked inside finished formats. Context engineering makes it useful at the moment of need: deciding what the application requires for a specific task and assembling the right pieces at the right time.
Consider a medical publisher with one body of authoritative clinical guidance. A researcher, a student, a practicing clinician, and an AI agent should not each receive the same chunk, the same level of detail, or the same rights treatment. Content engineering creates the components that make those different responses possible. Context engineering decides which components are appropriate for this user, this task, and this moment. One prepares the knowledge. The other activates it. Neither works without the other.
AI turns rights into a runtime decision
Rights used to live in contracts and rights-management systems, consulted occasionally and largely invisible to the content itself. That arrangement is ending. When an assistant assembles content on the fly, a rights decision sometimes has to happen at the same speed as retrieval. Rights metadata can no longer sit apart from content metadata.
This is where the useful idea is rights-aware content: content that effectively carries the knowledge of what can be done with it, by whom, where, and under what conditions. Increasingly, publishers need to be able to answer, at the level of an individual piece of content: Can this be searched? Summarized? Translated? Adapted? Used in retrieval? Used to train a model? Shown verbatim? Used to generate an assessment? Licensed into another AI product? In which geography, and for which customer?
Those permissions cannot stay buried in legal files while content flows through automated pipelines. They have to travel with the content.
In practice this is concrete: an assistant may be allowed to retrieve a paragraph to ground an answer but not reproduce it verbatim, or a knowledge object may be licensed for one customer or geography and not another.
The rights model also has commercial implications. In its pre-publication Part 3 report on generative AI training, the U.S. Copyright Office emphasized that fair use remains fact-specific and recommended allowing licensing markets to continue developing, noting that voluntary licensing is already emerging across several sectors (U.S. Copyright Office, Part 3, 2025). Handled well, rights become a revenue line. Wiley, for example, reported $49 million in AI revenue in fiscal 2026, up 23%, with lifetime AI revenue surpassing $110 million, and describes that revenue as increasingly recurring rather than one-off (Wiley FY2026 results).
The defining business question follows directly: how does a publisher make its knowledge available to AI without giving away the asset that makes it valuable? That question can only be answered per piece of content, which is why rights are becoming a runtime decision.
Provenance is the next opportunity, and most publishers already hold the raw material. As synthetic answers become abundant, users increasingly care why they should trust one. Publishers can expose the evidence chain, the author, edition, source, citation, review status, date, rights, and supporting material, as part of the AI experience itself. That turns provenance from a governance obligation into a product feature, and into something generic AI answers struggle to match. Trust, in other words, can become part of the product.
Discovery follows the same logic. The useful question is not only how to appear in an AI answer, but what the publisher wants that visibility to do. Optimizing for citation is a different bet than optimizing for licensing, API consumption, embedded use, or a publisher’s own AI experiences. Each implies a different way of exposing knowledge, and different publishers will choose differently.
Design knowledge for assembly, not just delivery
There is now a second consumer of a publisher’s knowledge, and it does not behave like the first. A human consumes a finished experience. An AI application may consume fragments and then assemble a new experience on the spot. That difference changes the design requirement. Publishers increasingly need to design knowledge for assembly, not only for delivery. “Content for machines” is becoming common language; designing for dynamic assembly is the more demanding and more interesting idea.
The resulting architecture connects these layers: authoritative knowledge/IP, decomposed into structured knowledge objects, wrapped in a rights and provenance layer, assembled in context, and delivered into many human and machine experiences from the same foundation.
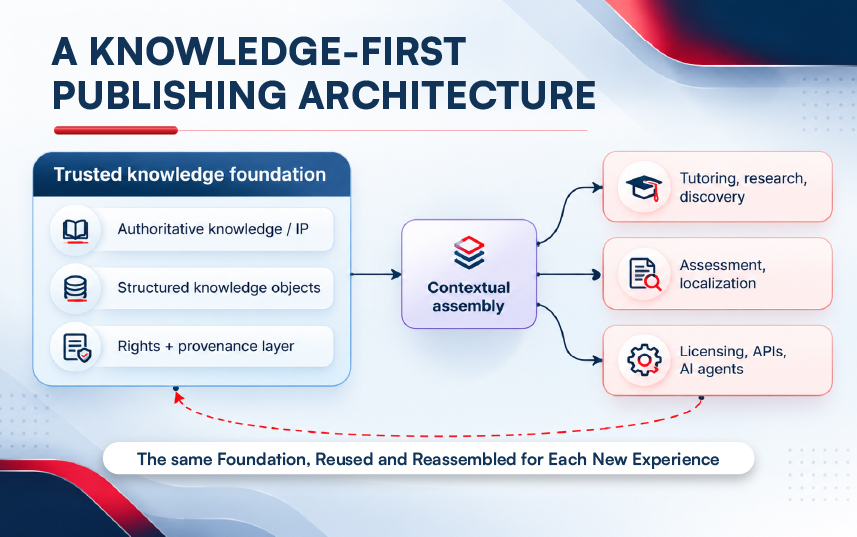
The value of building it this way is economic, and it is the main reason to care about content engineering at all. A shared knowledge foundation lowers the marginal cost of the next product, format, geography, or AI experience. Without it, every AI experience becomes another expensive one-off, with its own content pipeline to build and maintain. What makes the difference is shared infrastructure underneath: reusable knowledge components, common services and metadata, assessment objects, APIs, and shared governance and orchestration, so each new experience draws on the same foundation rather than rebuilding it.
This is the difference between adding AI features and redesigning the content operating model for AI. Bolting an assistant onto an existing product is a feature. Building a foundation from which tutoring, research, assessment, discovery, localization, and licensing experiences can all be generated is a different operating model. The strategic advantage will increasingly come from avoiding a separate content pipeline for every AI experience.
A fair caution: publishers will not all travel this road at the same speed. An education publisher, a scientific or medical publisher, an assessment organization, and a trade publisher do not share a business model, and the sequence and commercial logic will differ across them. The direction is common. The pace and the priorities will not be.
The question worth asking
Experienced publishing leaders already know they need an AI strategy. Perhaps the more useful starting question is not “what is our AI strategy?” but “what can our knowledge uniquely enable in an AI-mediated world?” That question puts the asset, the knowledge, back at the center, where the durable advantage actually sits.
Publishers have spent decades building trusted knowledge. The next advantage will come from making that knowledge as usable, governable, and valuable to machines as it already is to people.